

Pregunta 1
Oliver Habryka
x.com/ohabrykaLightcone Infrastructure and LessWrong lead who argues for slowing AI capabilities now through direct regulation and, in time, international treaties.
¿Cómo cambiará la IA el mundo?
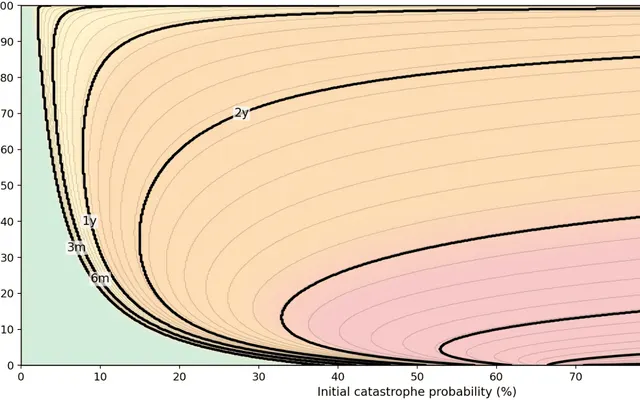
Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.
Doom–Bloom: 3 de 100. Escala de la transformación: 97 de 100. Rangos de interpretación: de 0 a 8 en horizontal y de 92 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.
>50%
“much more than 50% probability that deploying superintelligence would kill everyone”
Superintelligence killing everyone (human extinction)
Comment on “A case for courage, when speaking of AI danger” · jul 2025
IA general
My median for truly transformative AI is around seven years, with substantial probability on longer timelines.
Respuesta 1
Agrupados por hito, sin espaciarlos ni ordenarlos por fechas inferidas. La IA general y la IA sobrehumana conservan sus definiciones.
Un supuesto central
You are creating systems more capable than humans across the domains that determine who controls the future.Respuesta 1
Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?
Una pregunta sin resolver
I don’t have a supported unconditional number, because that also depends on whether humanity actually deploys it.Respuesta 3
¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?
Qué podría hacer cambiar de opinión
The biggest update would be a concrete, publicly legible demonstration that we can understand and reliably control systems approaching transformative capability—not merely make them pass alignment benchmarks.Respuesta 4
¿Qué evidencia bastaría y en qué dirección movería su visión?
Más detalles
Las pérdidas catastróficas o irreversibles ocupan un lugar central en el futuro esperado.
100 / 100
Rango de interpretación de 100 a 100 en la escala cualitativa.
Las decisiones humanas tienen una influencia significativa, aunque muy condicionada.
60 / 100
Rango de interpretación de 49 a 76 en la escala cualitativa.
Se espera que la IA siga siendo un conjunto de herramientas acotadas.
Se espera que la IA iguale a las personas en la mayor parte del trabajo cognitivo.
Posición simulada: Se espera que la IA supere ampliamente a las personas en el trabajo cognitivo.
Posición simulada: Detener o frenar considerablemente el desarrollo de IA más capaz.
Continuar el desarrollo con las salvaguardas indicadas.
Acelerar el desarrollo de IA más capaz.
Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.
Visiones similares
Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Oliver Habryka
Evaluación simulada
Fuentes
Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.
Argues that someone who ignores future people might rationally rush toward AGI, and that consistently accepting up to 1% extinction risk per year in exchange for faster AI would more likely than not end humanity within a century. He then states his own view: he assigns much more than 50% probability that deploying superintelligence would kill everyone, while saying that claim needs more thinking through than the usual “at least 10%” argument. The figure is conditional on deployment and gives no date. The actuarial table is ChatGPT output he cites. Full comment inspected; older context, but no newer number was found.

Answering Daniel Kokotajlo’s question about alternatives to the AI 2027 slowdown-ending alignment plan, Habryka offers his own: do not build AGI for a long time, probably make smarter humans, build better coordination technology so scaling can be careful, and do an enormous amount of interpretability in the decades that buys. A short sketch, not a worked-out program. In an adjacent reply the same day he calls the slowdown ending the “lucky” ending and guesses that working on a plan that does not need extreme luck, plus pushing timelines back, would have 20–30 times more impact. Kokotajlo’s plan description is not his.

Argues that Claude weights hosted in ordinary Amazon, Google and Microsoft data centers are probably not protected from corporate espionage teams as Anthropic’s RSP commits, so Anthropic is probably out of compliance. He says the choice is not that reckless and that he does not know whether better lab security is good or bad for the world. This is a compliance argument about one company, not a catastrophe forecast; the Microsoft postscript is explicitly low-confidence. Full post inspected; linked Claude outputs and Anthropic’s quoted RSP text are not his views.

Says the best way he knows to improve the world is to help humanity realize that AI will be a big deal, probably reasonably soon, and to inform decision-makers about the likely consequences of their plans. He agrees AI 2027’s timelines are too short and has other disagreements, yet expects reality to look closer to it than to any other story. He calls If Anyone Builds It, Everyone Dies a higher-fidelity message about what he cares about most. A fundraising appeal: impact and credit estimates for his own organization are self-assessments. AI-related sections inspected.

Rejects the person-affecting stance, which counts only currently living people, as a basis for societal decisions about when to build superintelligence. He compares it to someone who personally does not want to die and is indifferent to harming others, and says applying it to past generations would have meant gambling everything on tenuous chances of immortality, probably ending in extinction. A critique of the paper’s framing, not a probability estimate. Full comment inspected; the paper’s arguments are not his.

Recounts that around 2023 he and others urged policymakers to slow capabilities directly, for example through training-compute limits, while most of the safety ecosystem invested in conditional if-then commitments, evals and RSPs. He says no company or country adopted real if-then commitments and calls that effort a huge waste, urging people to switch to direct, immediately acting policy. His account of the history; he expects disagreement. Full comment inspected.

Says a short pause in recent years would mainly have helped by making future pauses likelier, and that he would ideally halt around the capability level he expects in early 2027. With no global pause close, he thinks “stop as soon as possible” is right. He wants regulation that cuts capability growth now: liability, datacenter moratoriums, GPU taxes or tariffs, auditing, even partial nationalization, with treaties in the long run, and thinks licensing might backfire. He says policymakers who grapple with existential risk usually conclude preventing superintelligence is paramount. Full comment inspected; the quoted commenter is not him.

Through parables, argues that anyone concentrating power in the name of goodness should first ask whether that power can be defended from corruption and adversaries. He applies this to his own rationality, EA and AI safety communities, fearing they conquered more than they can defend, and says he sometimes considers quitting. He grants that coordination problems are real and does not oppose all centralization. The “20 AI companies racing versus one in the lead” argument is an objection he voices, not his view. Full post inspected.

Replying to a claim that the critical period is at most five years, he says timelines look shorter than before but it would be dogmatic hubris to stop planning for longer ones. States a median of about seven years until truly transformative AI, with substantial probability on longer. A timeline for transformative AI, not for superintelligence or catastrophe. Full comment inspected.

A list of unwritten post ideas. The AI-relevant item summarizes his history: OpenAI and Anthropic seemed like really bad bets, Anthropic’s RSP seemed really dubious, and he believes events proved him right, as with FTX. Other items (fire codes, courts, lighting, good-faith discourse) are unrelated to AI. Sketches rather than full arguments. Full post inspected.

Habryka says AI existential risk is a cursed problem with no real “direct work” that solves it. Most lab researchers’ impact comes from building a culture less likely to deceive itself about alignment difficulty, which enables policy advocacy and eventually international cooperation. He says alignment benchmarks do not track the problem well. Mostly about funding and incubators, which are not AI forecasts. Own turns in the speaker-labeled section on direct versus meta work inspected; the host warns the AI-edited transcript may distort wording.

Argues that ten safety people inside a lab cannot align AIs or do anything useful with them without a concrete plan shared with others. He sees the most valuable part of control work as catching early AIs misbehaving and channeling that evidence into a substantial slowdown or pause. He says AIs will be caught subverting safety systems routinely, and the hard problem is training that out without producing deceptive alignment; he thinks recent evidence supports him. He still rates Redwood’s strategy above almost anyone else’s. Full comment inspected; quoted lines are Mallen’s.

¿Dónde te ubicas?
Mapear mi visión de la IA