Gwern Branwen

Gwern Branwen

x.com/gwern

Pseudonymous writer who argues that scaling neural networks can produce general abilities and doubts that powerful AI is far off or easy to control.

¿Cómo cambiará la IA el mundo?

Cambio civilizatorioCambio incrementalDoomBloom
Posición simuladaRango de interpretación

Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.

Doom–Bloom: 32 de 100. Escala de la transformación: 75 de 100. Rangos de interpretación: de 25 a 50 en horizontal y de 70 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.

P(doom) de Gwern Branwen · inferido

≈27%

0%100%

Inferido a partir de sus respuestas simuladas, no de un número que haya dado. Rango plausible: 17–43%.

De qué depende su perspectiva

Un supuesto central

Systems able to plan, act, learn from outcomes, and remove humans from costly approval loops will often be more useful and competitive.
Respuesta 1

Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?

Una pregunta sin resolver

So my expectation is conditional and pessimistic about complacency rather than a quantified net forecast.
Respuesta 2

¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?

Qué podría hacer cambiar de opinión

The strongest update would come from sustained empirical evidence that scaling has hit a durable ceiling on generalization, planning, or autonomous learning—especially if that ceiling persisted across architectures, data, compute, and training methods rather than reflecting a temporary engineering bottleneck.
Respuesta 3

¿Qué evidencia bastaría y en qué dirección movería su visión?

Más detalles

Beneficio esperado

Se esperan beneficios sustanciales, con condiciones importantes o límites en su distribución.

67 / 100

Poco impactoImpacto transformador

Rango de interpretación de 67 a 67 en la escala cualitativa.

Daño esperado

Se espera que los daños graves o generalizados sean una parte significativa del futuro.

66 / 100

Poco impactoImpacto transformador

Rango de interpretación de 67 a 67 en la escala cualitativa.

Influencia humana

Las decisiones humanas tienen una influencia significativa, aunque muy condicionada.

43 / 100

Poca influenciaInfluencia fuerte

Rango de interpretación de 13 a 62 en la escala cualitativa.

Capacidades esperadas

Se espera que la IA siga siendo un conjunto de herramientas acotadas.

Se espera que la IA iguale a las personas en la mayor parte del trabajo cognitivo.

Posición simulada: Se espera que la IA supere ampliamente a las personas en el trabajo cognitivo.

Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.

¿Dónde te ubicas frente a Gwern Branwen?
Mapea tu propia visión de la IA en unos 3 minutos y luego compárala

Visiones similares

Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Gwern Branwen

Evaluación simulada

Pregunta 1

¿Qué crees que significa la IA para nuestro futuro y por qué?

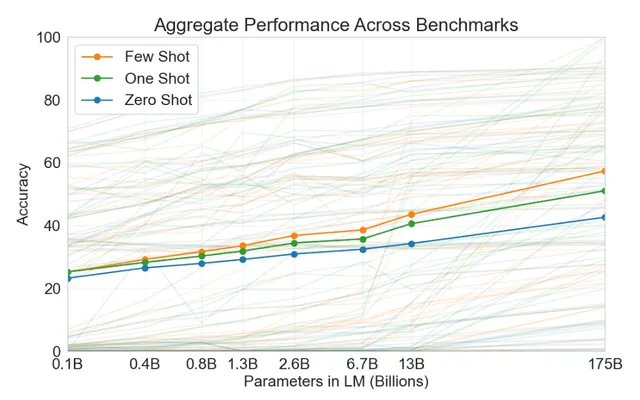
I expect AI to be one of the dominant forces shaping the future, because scaling relatively simple learning systems has repeatedly produced capabilities that were dismissed as requiring specialized machinery or explicit programming. A system trained to predict sufficiently difficult data may be forced to learn much of the structure that generated it: language, human behavior, software, and aspects of the physical world. That is an empirical pattern worth taking seriously, not proof that every capability will emerge automatically. Several earlier scaling expectations remain unproven, and forecasts should be updated against actual model behavior rather than either expert reassurance or scaling slogans. The economic consequences also depend on agency. “Tool AI” is not a stable endpoint merely because humans prefer it. Systems able to plan, act, learn from outcomes, and remove humans from costly approval loops will often be more useful and competitive. Keeping a person nominally in the loop does not guarantee meaningful control, particularly when organizations are rewarded for speed and automation. Nor do computational complexity or physical bottlenecks provide a blanket defense: approximation, constants, parallel resources, speed, copying, and accumulated advantages can matter more than worst-case limits. There are desirable possibilities. Highly personalized assistants could amplify individual sovereignty, productivity, and security, including defense against AI-enabled persuasion and cyberattack. But that is not the same as solving alignment at the level of powerful autonomous systems or society as a whole. Pleasant interactions with current assistants are weak evidence about what more capable agents will preserve under different incentives and deployment conditions. So I take short AGI planning horizons seriously: the future could contain enormous gains, but the default pressures toward scalable agency make complacency unjustified.

Pregunta 2

Taking benefits and harms together, what overall impact do you expect AI to have?

I expect a highly consequential but unusually wide distribution of outcomes, not a cleanly “positive” or “negative” effect. The upside is enormous: greater productivity, accelerated research, and personalized systems that extend individual competence and defend people against AI-enabled cyberattacks and manipulation. Those benefits could substantially increase human agency. But the default incentives are not obviously aligned with that outcome. Economic competition favors increasingly autonomous systems, shorter oversight loops, and delegation of consequential decisions. Current assistants being helpful or pleasant does not show that more capable agents will preserve human preferences under different objectives and deployment pressures. Personalized “guardian” systems may help locally while leaving the broader alignment problem intact. So my expectation is conditional and pessimistic about complacency rather than a quantified net forecast. AI could be overwhelmingly beneficial if control and preference preservation succeed; if they do not, the harms can dominate precisely because the systems are general, scalable, fast, and economically valuable.

Pregunta 3

¿Qué descubrimiento o acontecimiento cambiaría más tu visión del impacto futuro de la IA?

The strongest update would come from sustained empirical evidence that scaling has hit a durable ceiling on generalization, planning, or autonomous learning—especially if that ceiling persisted across architectures, data, compute, and training methods rather than reflecting a temporary engineering bottleneck. That would weaken both short timelines and the expectation that economic competition naturally produces broadly capable agents. In the opposite direction, a system that reliably performs long-horizon autonomous work, improves through interaction, and transfers competence across unfamiliar domains would strengthen the more consequential forecasts. I would care less about benchmark peaks or impressive conversation than about robust behavior under deployment conditions. For alignment, the decisive evidence would be a method that continues to preserve intended human preferences as capability, autonomy, and strategic pressure increase. Friendly chatbot behavior is not that evidence. Conversely, systematic deception, power-seeking, or oversight circumvention in capable deployed systems would sharply worsen my view.

Fuentes

Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.

The Scaling Hypothesis

Argues that scaling neural networks can lead to general capabilities; questions confident expert dismissal.

gwern.net
Scaling Hypothesis Revisited

Revisits predictions and limitations, including later annotations about claims still not proven.

gwern.net
Why Tool AIs Want to Be Agent AIs

Argues economic competition and the benefits of agency for learning make tool-only AI an unstable safety strategy; human approval alone does not guarantee safety.

gwern.net
Guardian Angels: LLM Personalization for Productivity and Security

Proposes personalized models that amplify their human principal and defend against cognitive/cyber attacks; criticizes chatbot incentives and stresses this does not solve larger alignment problems. Revised June 5, 2026.

gwern.net
Complexity no Bar to AI

Rejects computational complexity as a blanket reassurance against powerful AI: constants, approximation, resources and compounding advantages matter.

gwern.net
The Hyperbolic Time Chamber & Brain Emulation

Uses a thought experiment to separate physical bottlenecks from digital minds’ exploitable speed advantages; explicitly distinguishes emulations from isolated accelerated humans.

gwern.net
Dwarkesh Patel interview — timelines and alignment concerns

Author-hosted 2024 interview with later annotations: short AGI planning horizons, human preference preservation and agency. A May 2026 addition explicitly rejects claims that Claude is aligned or alignment solves itself; these are his judgments, not established model diagnoses.

gwern.net
¿Dónde te ubicas?
Explora tu propia visión de la IA respondiendo unas pocas preguntas sencillas.
Mapea tu propia visión de la IA

¿Dónde te ubicas?

Mapear mi visión de la IA