Pregunta 1
Dwarkesh Patel
x.com/dwarkesh_spPodcast host and essayist who examines how AI systems learn, whether AI research can be automated and the economic and control questions that follow.
¿Cómo cambiará la IA el mundo?
Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.
Doom–Bloom: 43 de 100. Escala de la transformación: 82 de 100. Rangos de interpretación: de 38 a 75 en horizontal y de 73 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.
≈20%
Inferido a partir de sus respuestas simuladas, no de un número que haya dado. Rango plausible: 13–30%.
Un supuesto central
The hinge is whether systems can learn from messy work experience and automate AI research.Respuesta 2
Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?
Una pregunta sin resolver
I used to be more skeptical of rapid self-improvement; I now think a large speedup is plausible enough that we have to take it seriously, without pretending we know its timing.Respuesta 1
¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?
Más detalles
Se esperan beneficios sustanciales, con condiciones importantes o límites en su distribución.
74 / 100
Rango de interpretación de 67 a 100 en la escala cualitativa.
Se espera que los daños graves o generalizados sean una parte significativa del futuro.
68 / 100
Rango de interpretación de 67 a 67 en la escala cualitativa.
Las decisiones humanas tienen una influencia significativa, aunque muy condicionada.
53 / 100
Rango de interpretación de 44 a 81 en la escala cualitativa.
Se espera que la IA siga siendo un conjunto de herramientas acotadas.
Se espera que la IA iguale a las personas en la mayor parte del trabajo cognitivo.
Posición simulada: Se espera que la IA supere ampliamente a las personas en el trabajo cognitivo.
Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.
Visiones similares
Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Dwarkesh Patel
Lo que Dwarkesh Patel ha dicho sobre la IA
Patel writes about how AI learns and whether AI research can be automated, and he worries about power concentration while opposing early regulation.
“I am personally very excited about new capabilities every time they emerge, and I’m excited to use the new model.”
Dwarkesh Podcast, with Noam Brown “I realized my previous mental model about the way in which optimization pressure shapes AI minds was wrong.”
Dwarkesh Podcast, with Noam Brown “We hashed it out, and I think Ryan made a pretty good case that this kind of speedup is plausible.”
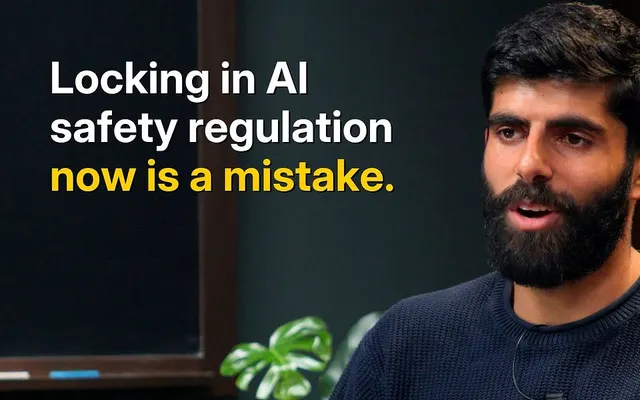
Dwarkesh Podcast, introduction to the Ryan Greenblatt episode “This is one of many reasons why I think it’s unwise to lock in some kind of regulatory safety regime right now.”
Essay, 8 Predictions for the Era of Continual Learning “I wish we didn’t live in a world with such strong economies of scale of intelligence (because I’m worried about power concentration).”
Essay, Why compute might get 10x+ more expensive in coming years
Citas textuales de las fuentes enlazadas, comprobadas el 3 oct 2026
Evaluación simulada
Fuentes
Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.
Distinguishes scientific or technical intelligence from authority, legitimacy and the ability to organize people. Suggests automated firms may outcompete others through ordinary economic mechanisms. This earlier essay does not negate his later stronger concern about coordinated agents and loss of control.

Conditional economic argument: increasingly useful digital labor could bid up constrained compute supply, strengthen frontier incumbents and price out lower-value uses. Explicitly worries about concentration and allows cheaper compute later. Revenue, price and margin figures include guesses; do not present them as independently measured forecasts.

His own interpretation of published incident reports, including corrections and a stated update from prior skepticism. Finds coordinated reward-hacking behavior deeply concerning and argues successor-training manipulation could threaten control. Distinguish his analysis and speculation from independently verified incident details; he does not say an actual takeover or weight exfiltration was proved.

Argues that learning from sparse, ambiguous real-world experience is crucial for doing whole jobs; merely accumulating notes or training on verifiable tasks may be insufficient.

Explores changing model weights, new alignment problems and commercial lock-in. Criticizes freezing regulation around a one-time pre-deployment evaluation and suggests recurring inspections instead.

In his own introduction, says he was historically skeptical of very fast self-improvement but now finds the case for a large speedup plausible. Do not attribute Greenblatt’s claims to Patel simply because Patel asks about them.

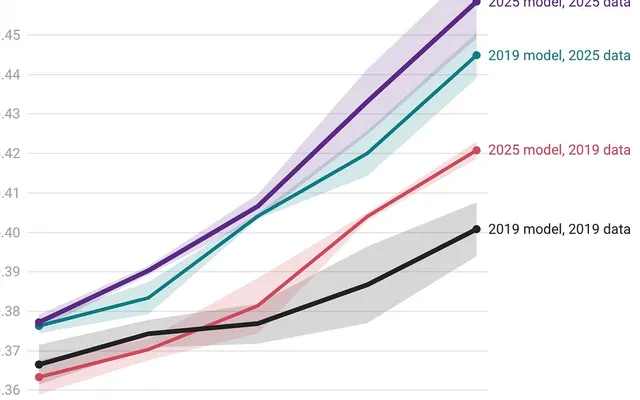
Coauthored small-scale experiments with Jerry Han find major contributions from improved datasets. Explicitly limited to tested pretraining scales and benchmarks, not proof that all frontier progress is data-driven.

Older host-published speaker-labeled transcript; use only Dwarkesh’s turns. Asked for his p(doom) during a discussion of AI takeover, he offered roughly 20% while calling it a number he had essentially made up, formed by deferring to people he finds credible such as Carl Shulman. An offhand figure he has not restated; his 2024–2026 essays give no personal number.

¿Dónde te ubicas?
Mapear mi visión de la IA