
Alex Zhang

Alex Zhang

x.com/a1zhang

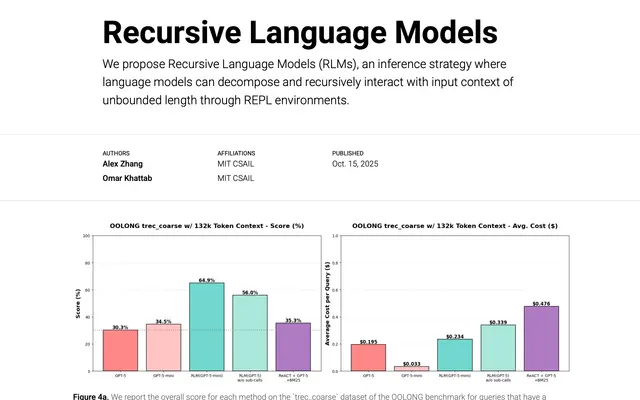
AI researcher who builds benchmarks and studies how scaffolds and recursive model calls can get more out of existing language models.

¿Cómo cambiará la IA el mundo?

Cambio civilizatorioCambio incrementalDoomBloom
Centro del rango sin resolverRango de interpretación

Horizontal: su perspectiva Doom–Bloom expresada. Vertical: escala de la transformación.

Doom–Bloom: 57 de 100. Escala de la transformación: 50 de 100. Rangos de interpretación: de 49 a 62 en horizontal y de 0 a 100 en vertical. Son coordenadas de interpretación, no probabilidades de eventos.

P(doom) de Alex Zhang

Aún sin estimar

Sus respuestas simuladas no dicen lo suficiente sobre el riesgo catastrófico para estimarlo.

Cómo estimamos P(doom)

De qué depende su perspectiva

Un supuesto central

Better models and better harnesses are complementary: training expands what components can do, while scaffolding determines whether those abilities combine into reliable performance.
Respuesta 1

Si este supuesto resultara distinto, ¿cómo cambiaría su perspectiva?

Una pregunta sin resolver

I don’t have a well-supported overall societal forecast.
Respuesta 2

¿Qué le ayudaría a distinguir aquí entre los desenlaces plausibles?

Qué podría hacer cambiar de opinión

If learned decomposition and recursive inference let models solve genuinely novel, out-of-distribution tasks—not merely longer versions of familiar benchmarks—that would strengthen my expectation of rapid capability gains from better harnesses.
Respuesta 4

¿Qué evidencia bastaría y en qué dirección movería su visión?

Más detalles

Beneficio esperado

Se esperan beneficios sustanciales, con condiciones importantes o límites en su distribución.

62 / 100

Poco impactoImpacto transformador

Rango de interpretación de 33 a 67 en la escala cualitativa.

Influencia humana

Una estimación provisional a partir de tus respuestas; el rango más amplio muestra otras lecturas plausibles.

51 / 100

Poca influenciaInfluencia fuerte

Rango de interpretación de 0 a 100 en la escala cualitativa.

Estas interpretaciones conservan las condiciones que se indicaron. Los beneficios y los daños pueden ser considerables a la vez. Los rangos describen cómo leemos sus respuestas simuladas, no intervalos de confianza estadísticos.

¿Dónde te ubicas frente a Alex Zhang?
Mapea tu propia visión de la IA en unos 3 minutos y luego compárala

Visiones similares

Líderes de opinión cuyas visiones simuladas son las más cercanas a la de Alex Zhang

Fuentes

Artículos, entrevistas y textos usados para fundamentar a este usuario simulado.

Evaluación simulada

Pregunta 1

¿Qué crees que significa la IA para nuestro futuro y por qué?

I think AI’s future depends not only on building larger or better-trained models, but on learning how to use the capabilities models already have. Today’s systems are often placed inside brittle, human-designed workflows that ask for one enormous leap instead of decomposing a problem, inspecting intermediate results, and recursively allocating computation. Better scaffolds can turn an unfamiliar task into a composition of familiar subproblems, while recursive language-model systems can work over information far beyond a single context window. That makes me optimistic about substantial capability gains from inference-time methods and learned decomposition. But it does not imply that scaling or training is finished. Better models and better harnesses are complementary: training expands what components can do, while scaffolding determines whether those abilities combine into reliable performance. The main epistemic challenge is measuring this honestly. A model can dominate a leaderboard because it recognizes familiar benchmark structure or has encountered related data, yet still fail when an agent must generalize in a genuinely new environment. Simply making tasks longer does not solve that problem. We need benchmarks that test useful out-of-distribution generalization and reveal whether a harness is actually helping rather than exploiting benchmark regularities. I expect much of AI progress to come from jointly improving models, computation, decomposition, and evaluation—but benchmark advances alone do not establish a particular forecast for society as a whole.

Pregunta 2

Considerando en conjunto los beneficios y los daños, ¿qué impacto general esperas que tenga la IA en nuestra sociedad?

I don’t have a well-supported overall societal forecast. My work supports a narrower expectation: AI systems may become substantially more capable through better scaffolding, recursive computation, and evaluation, even without every gain coming from larger models. That could expand both useful applications and the harms available to capable systems, but benchmark or harness progress alone does not tell us which effects will dominate. The key mistake would be to infer social outcomes directly from technical performance. A model solving long-context tasks through decomposition, or succeeding on a cleaner generalization benchmark, establishes something about capability—not deployment incentives, access, governance, labor effects, or distribution of benefits. So I expect meaningful capability gains, but I would not turn that into a confident claim that AI’s net societal impact will be positive or negative.

Pregunta 3

¿Cuál es tu estimación intuitiva de la probabilidad de que la IA cause la extinción humana o una catástrofe permanente similar?

I don’t have a defensible numerical estimate. My work suggests that better scaffolding and recursive computation could unlock capabilities faster than raw model scaling alone would indicate, which matters for risk assessment. But translating that technical possibility into an extinction probability requires assumptions about future systems, deployment, control, access, and governance that my research does not establish. So I would not attach a percentage to it.

Pregunta 4

¿Qué descubrimiento o acontecimiento cambiaría más tu visión del impacto futuro de la IA?

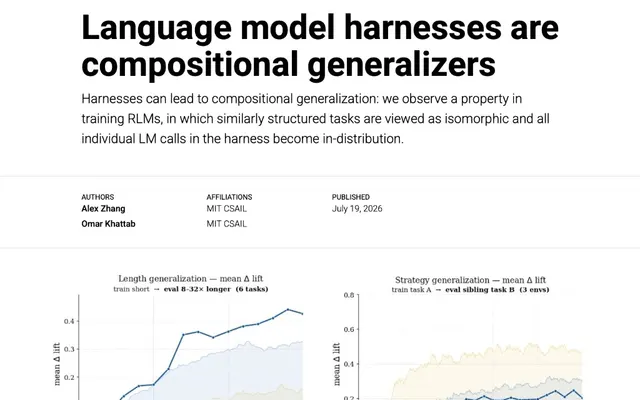
The most important technical update would be strong evidence about whether capabilities reliably compose. If learned decomposition and recursive inference let models solve genuinely novel, out-of-distribution tasks—not merely longer versions of familiar benchmarks—that would strengthen my expectation of rapid capability gains from better harnesses. Conversely, if these methods consistently hit hard ceilings because errors compound or models cannot generate useful decompositions, I would put more weight on improvements from training and scaling. For overall societal impact, though, a technical discovery would not be enough. I would update most from real evidence about deployment: whether increasingly capable systems remain controllable and auditable, who gains access, how institutions respond, and whether benefits and harms are broadly distributed. Capability benchmarks can tell us what systems may be able to do; they cannot by themselves determine what society will do with them.
¿Dónde te ubicas?
Explora tu propia visión de la IA respondiendo unas pocas preguntas sencillas.
Mapea tu propia visión de la IA

¿Dónde te ubicas?

Mapear mi visión de la IA